15 years
Engineering
I'm a software engineer in Ankara. I've been doing this for fifteen years, most of them designing and running distributed systems on the JVM. From the end of 2023 I worked at Huawei Big Data on the internals of Apache Spark and then on Apache Iceberg; the project ended in September 2026.
Now I work independently and I'm open to fully remote work, contract or full-time, on backend and distributed systems on the JVM as well as on Spark, Iceberg and the data platforms built on them. I don't take office or hybrid roles. I work in English, I've spent years in international teams, and I'm on UTC+3.
Alongside that I build my own things: a desktop tool for Iceberg metadata, a statusline for Claude Code, a documentation kit, puzzle games for my kids. When something takes me a while to understand and I can save someone else that time, I write it up.
Open to fully remote work, contract or full-time, on JVM backends, distributed systems and data platforms.
Experience
2023–2026
Huawei Big Data · Senior software engineer, Spark and Iceberg (through a vendor)
I started on Apache Spark, working on the optimiser, Kubernetes and the cache layer. In 2026 I moved to Apache Iceberg, mostly primary-key tables and the Spark and Flink paths that write and read them. The project ended in September 2026.
- Designed and built pluggable merge engines for Iceberg primary-key tables with Paimon's semantics (deduplicate, first-row, partial-update, and aggregation with eight functions), on Spark 4.0 writes and reads, columnar reads included. I also wrote the design document and the user manual.
- Spark SQL column DEFAULT values on Iceberg v3 tables, verified on four catalogs, and Flink SQL streaming reads of row-level changes from Iceberg upsert tables.
- Noticed that CI had been silently skipping most Flink test classes after a Hive upgrade and fixed it, so 183 of 184 classes run again and the test methods went from 1,282 to 4,456. Measured lazy metadata.json parsing with JMH and advised against it, because reads got 21–62% cheaper but commits 1.3–1.7× more expensive.
- On Spark, before Iceberg, a Kubernetes admission webhook in Go that lets executors use the Vertical Pod Autoscaler, a cluster manager in place of YARN, pre-caching and token renewal for the internal cache layer, and the upstream merge-scalar-subqueries optimisation.
- In 2025 I taught the Spark and the Flink lectures of a Big Data course at Sivas Cumhuriyet University, with colleagues teaching the other parts.
Apache Iceberg, Apache Spark, Flink, Paimon, Kubernetes, Java, Scala, Go, Python
2017–2023
Atlassian · Software engineer, distributed systems
Six years on the systems behind on-call scheduling and notifications, much of it in a remote team. I designed distributed systems and kept them running through acquisitions, office closures and layoffs.
- A zero-downtime migration of the legacy scheduling system from a monolith to microservices, in use by millions of people worldwide.
- The distributed on-call event systems, and 99.9% uptime for a global notification service that never stops, on AWS (DynamoDB, SQS, SNS).
- Fast triage of delivery problems and the technical writing that let the rest of the team fix the next one without me.
Java, Kotlin, Spring, AWS
2013–2017
MilSOFT · Software engineer, defence
Integration testing for defence systems. The tools for it did not exist yet, so we built them.
- Led an in-house Java test and emulation tool from design to deployment; it unblocked integration testing and debugging for other projects.
- Worked across networking, multithreading, communication protocols, resource limits, logging and custom parsers, with performance in mind throughout. Also wrote a 12-bit JPEG parser in C++.
Java, JavaFX, Swing, C++
2012–2013
AnelARGE · Software engineer, network security R&D
An R&D company working on network security. My job was mostly connecting systems built on different technology stacks.
- A communication backbone on WSO2 ESB that connected the company's technology stacks.
- An Apache web server module in C that handles requests by criteria read from a database.
- Visualisation work in Eclipse RCP.
Java, C, WSO2, Eclipse RCP
2011
ExtremePACS · Software engineer, healthcare
A healthcare startup. We practically lived in the hospitals we were building for, everyone did several jobs at once, and the procedures were still being written.
- Picture archiving (PACS) and radiology information (RIS) systems in .NET, from requirements to delivery in the hospital.
- Internal deployment tools that removed the manual steps.
C#, .NET, Silverlight, WCF

Bilge Baykuş
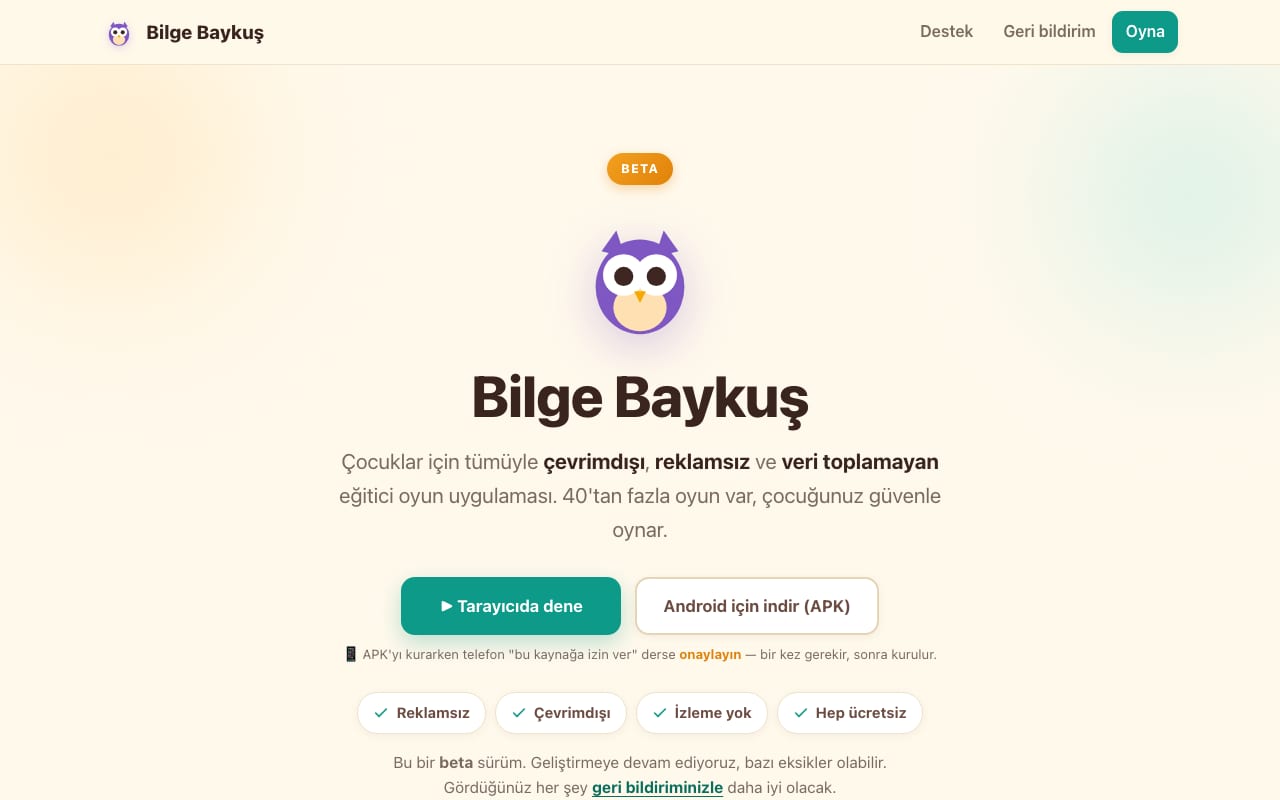
livePuzzle games for children in Turkish. There are more than forty, and all of them play offline, on the web and on Android.
havasaha
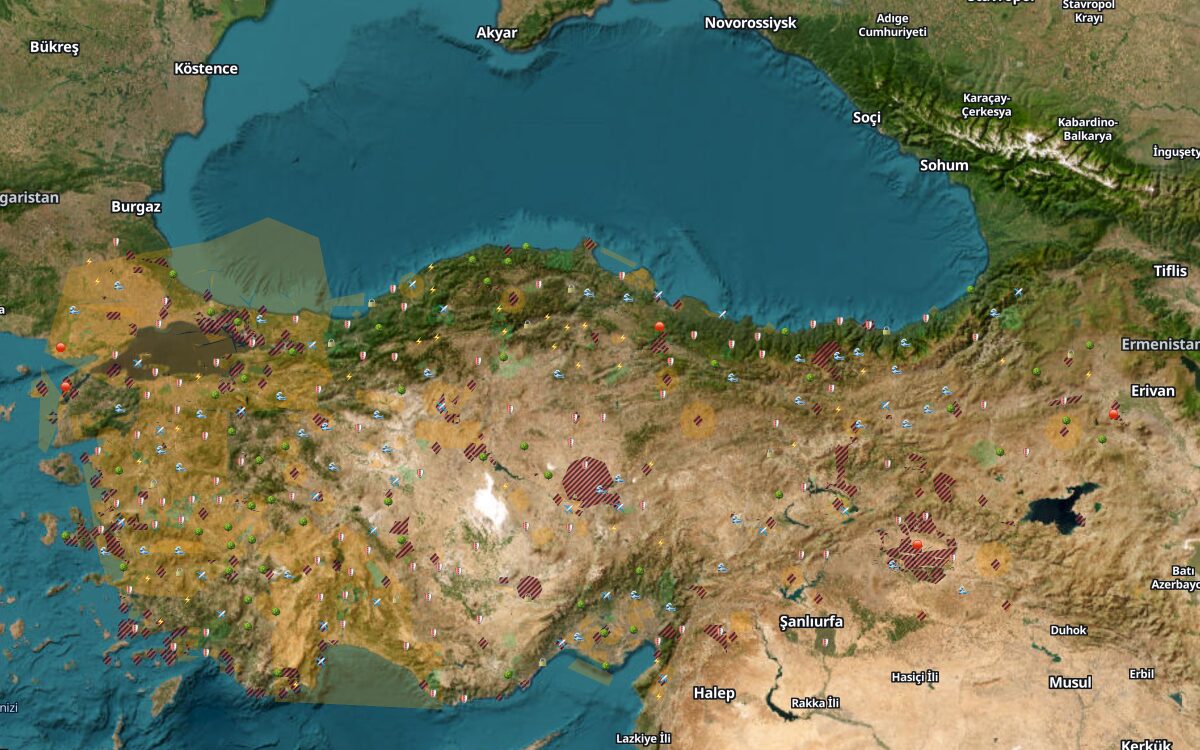
liveA map of where drones may and may not fly in Türkiye, with SHGM zones, temporary NOTAM restrictions, 3D terrain and the day's sun times. It is free and needs no account.
Iceberg Lens
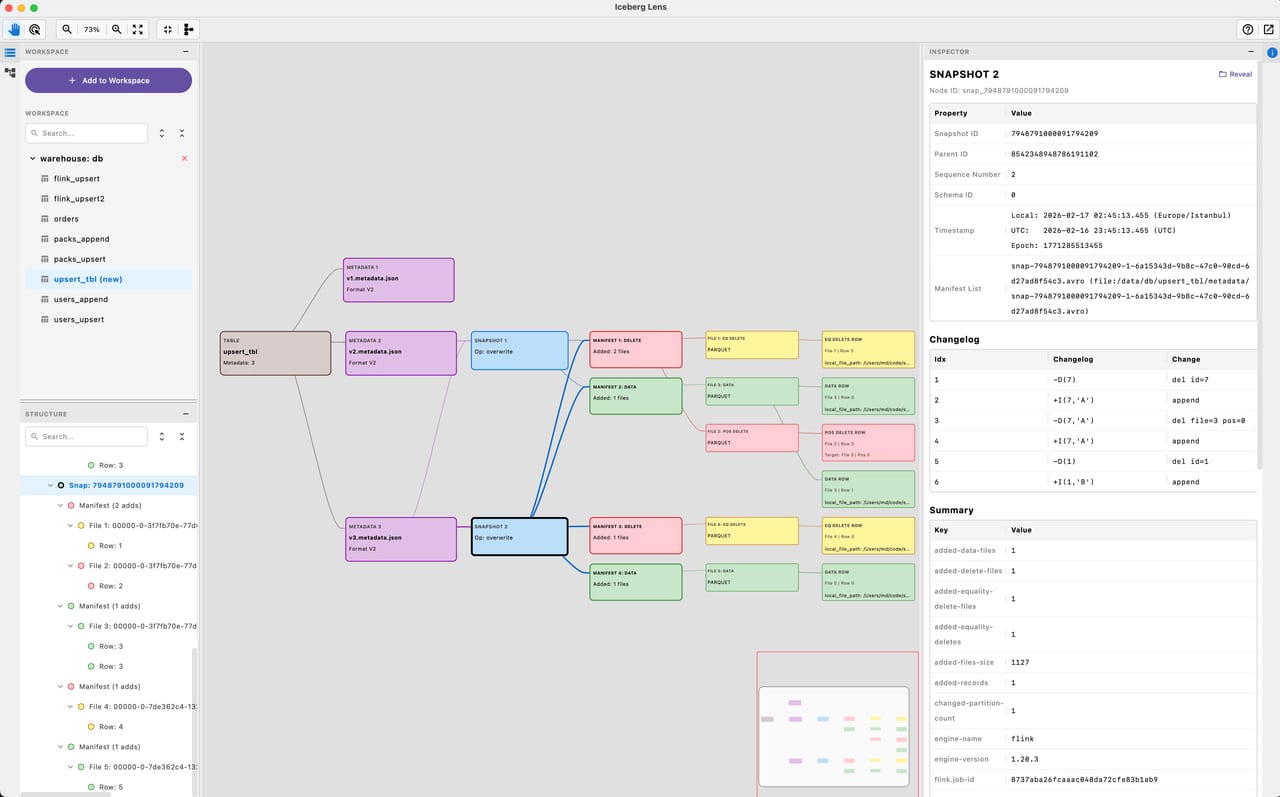
liveA desktop tool that draws an Iceberg, Paimon or Delta Lake table's metadata as a graph you can walk snapshot by snapshot, and checks every recorded figure against the files. It also runs in IntelliJ and as a CLI.
claude-quota
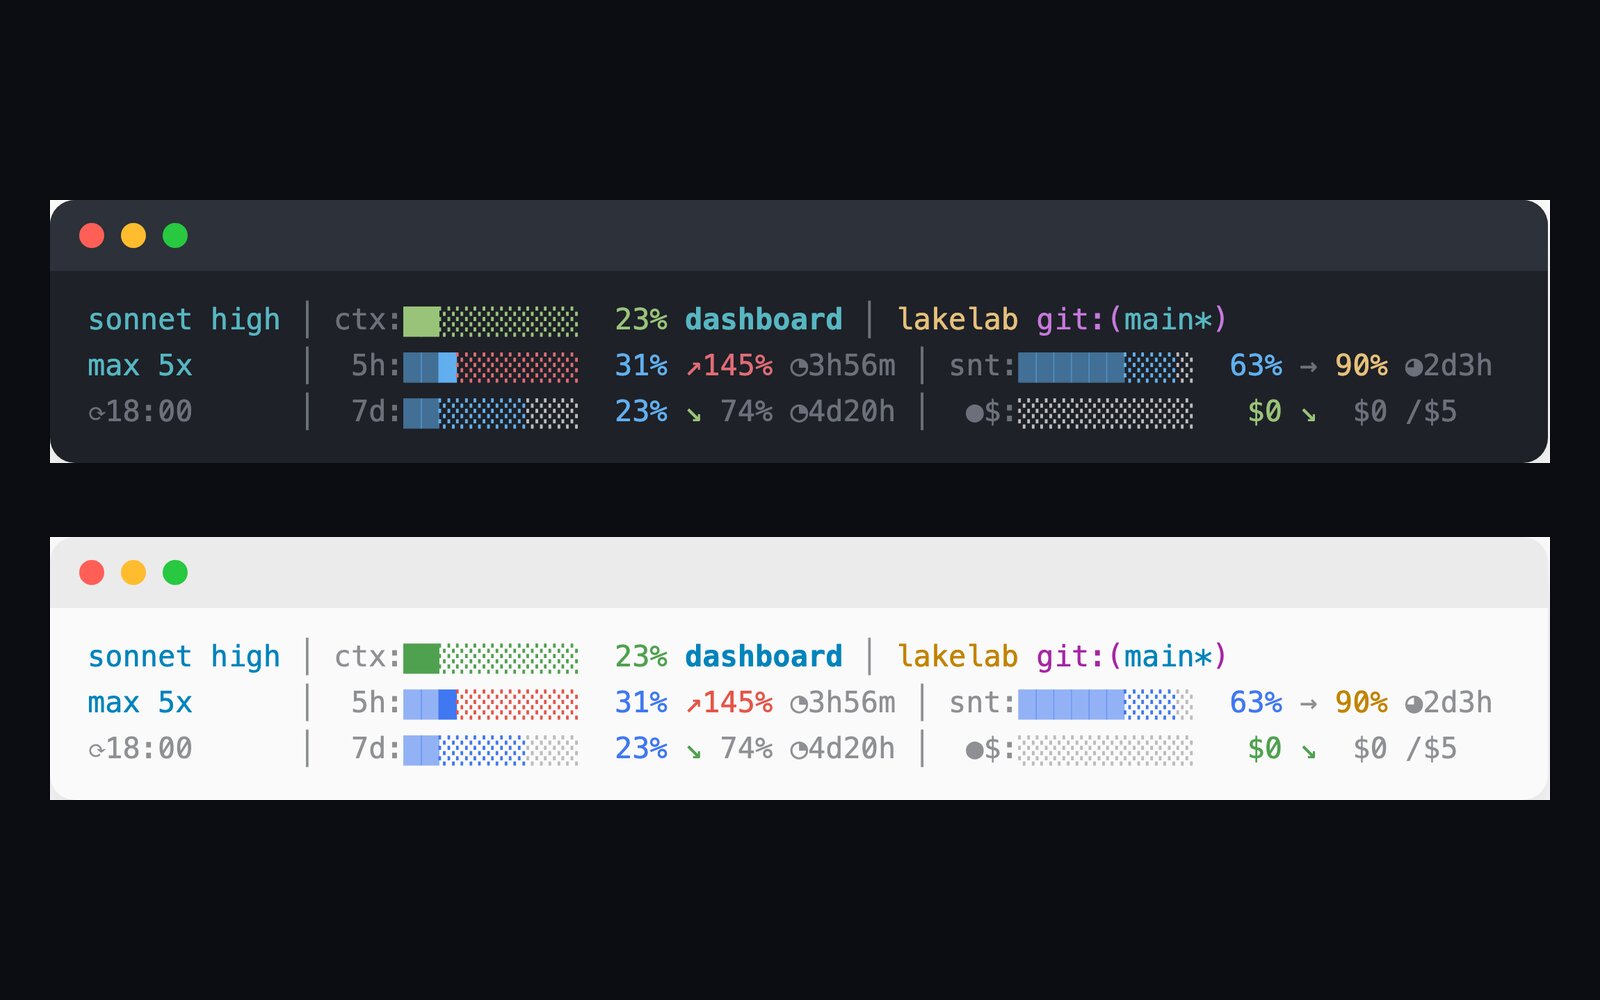
liveA Claude Code statusline that keeps every usage quota in view while you work. A pace arrow shows whether a window will run out before it resets.
oku
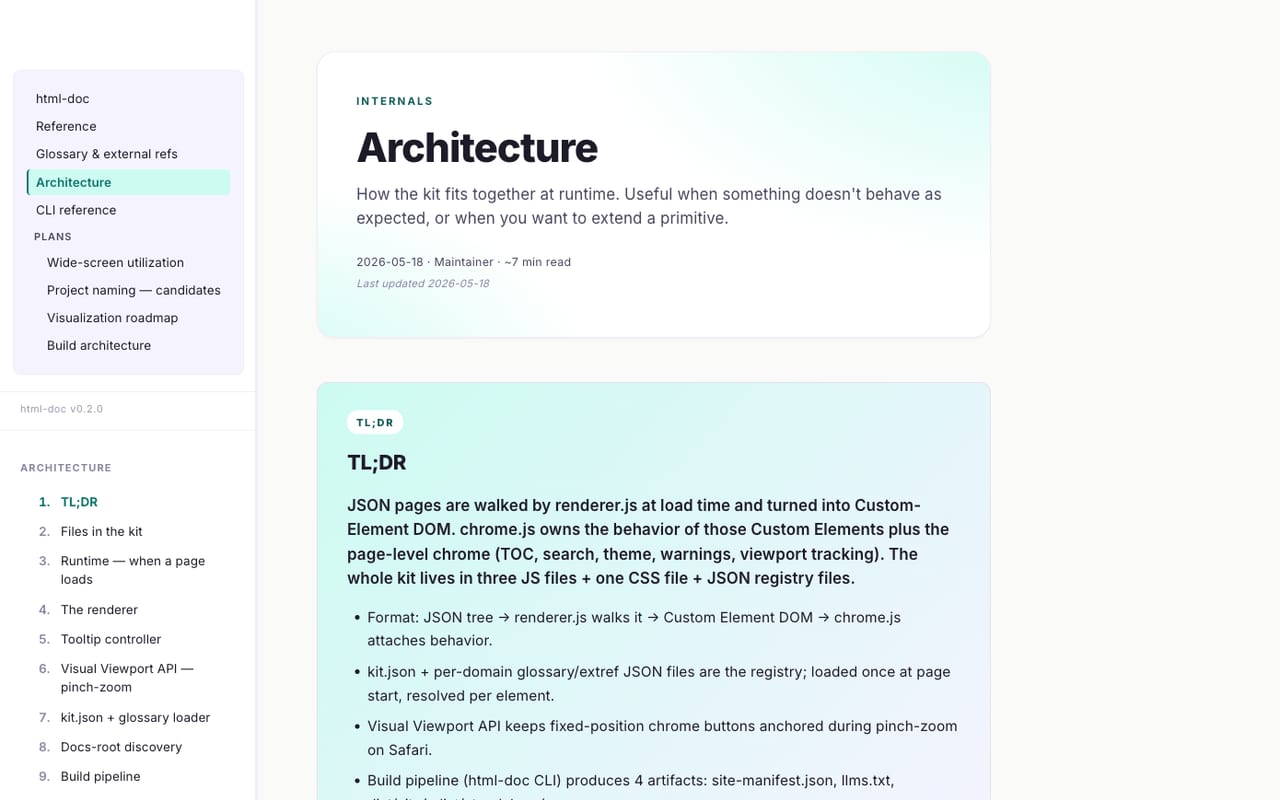
liveA documentation kit. Pages are written in Markdown and rendered in the browser, and one command builds a searchable site, an llms.txt and a single-file copy of every page.
LogMerge
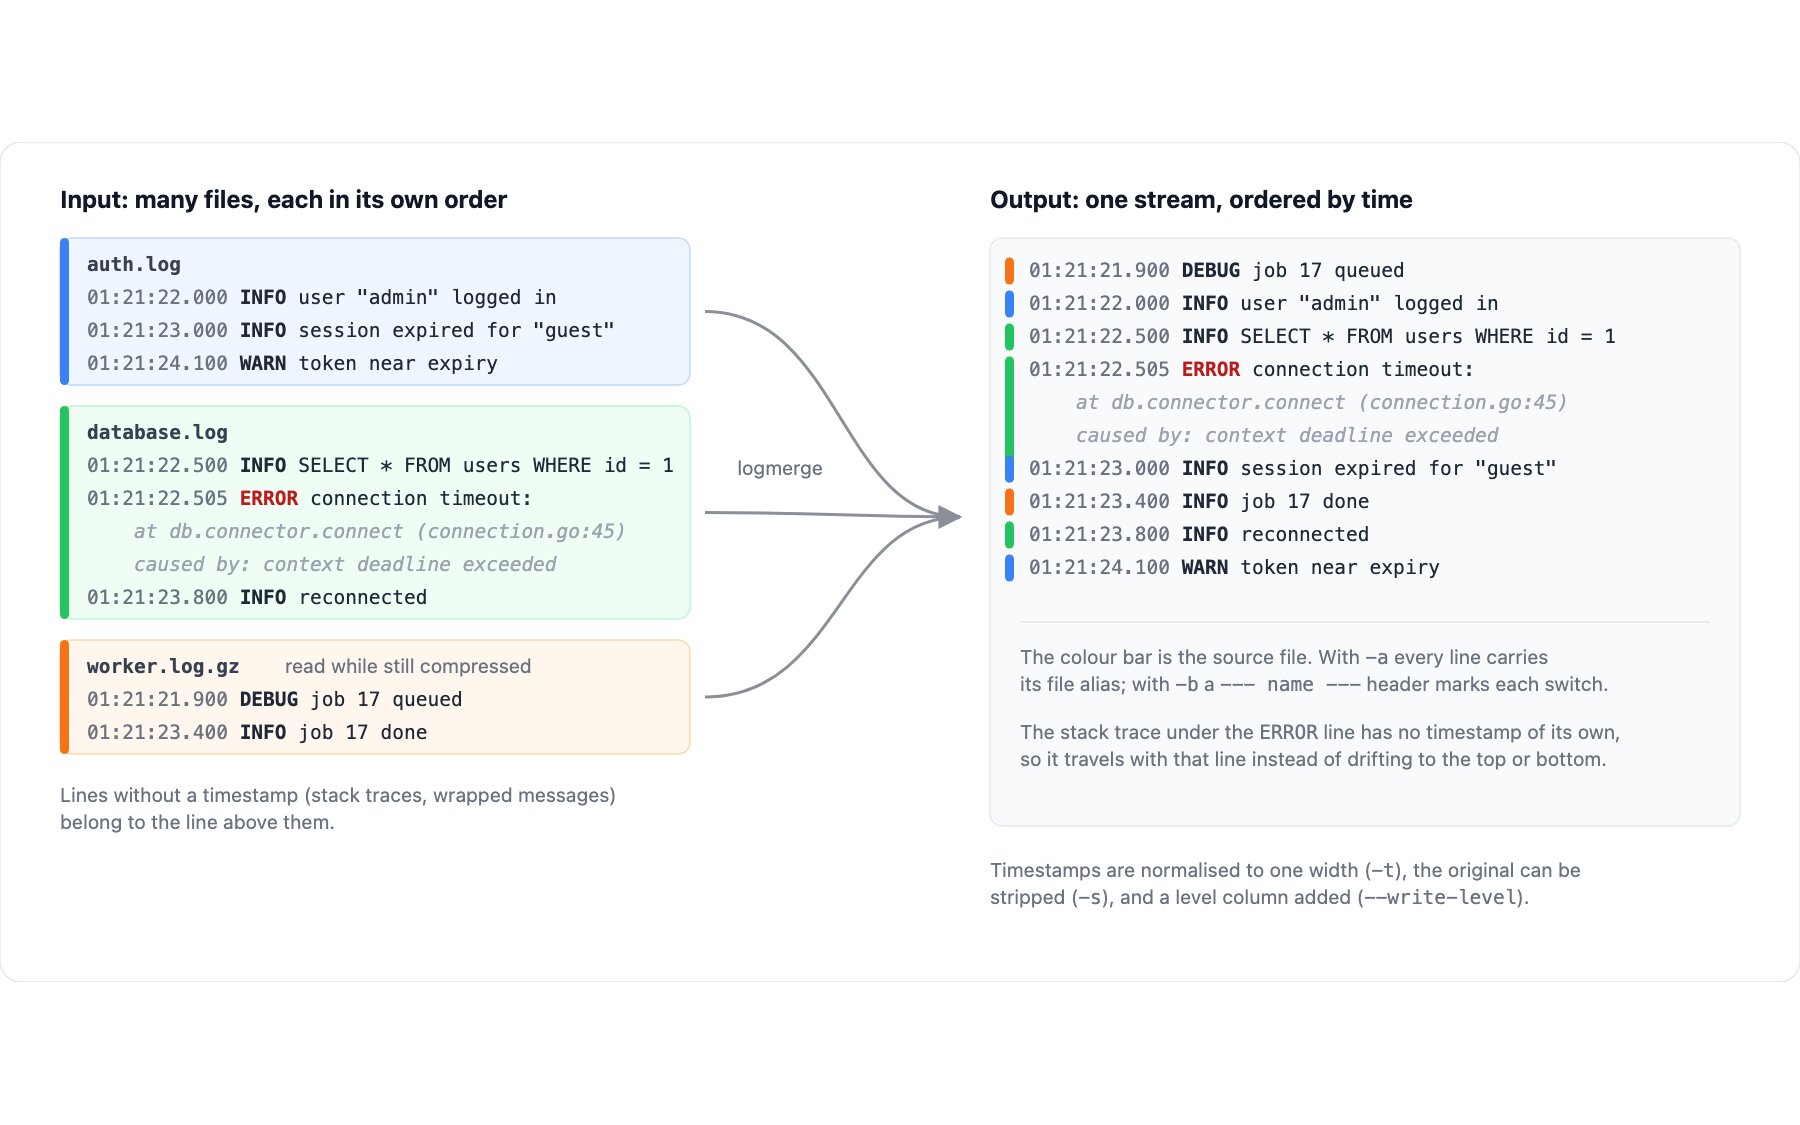
liveMerges many log files and archives into one stream in timestamp order. On an M1 Max it reads about 1 GB/s from disk.


-
Stop Reading Iceberg Manifests by Hand
A new tool to make Apache Iceberg metadata exploration faster and easier: Iceberg Lens. It turns complex metadata into an interactive graph with detailed inspection, designed for debugging and understanding table structure without manual file parsing.
-
Design Challenge: Integrate Kubernetes VPA with Apache Spark
Exploring the challenges and design approaches for integrating Kubernetes Vertical Pod Autoscaler (VPA) with Apache Spark for efficient resource management.
-
Why I Switched From Backend to Big Data Engineer After 10+ Years
After over a decade of working as a backend engineer, I switched to a new domain. This post explores my unexpected transition into the world of Big Data and the motivations behind my career shift.


